Overview
Our client, a metadata operations team within a large media technology company, managed a high volume of inbound scheduling support emails from broadcast networks and affiliates. Each email required manual reading, classification, priority assignment, and Jira ticket creation — a time-intensive process prone to inconsistency, duplicate tickets, and SLA breaches. NeenOpal designed and deployed an end-to-end AI-driven triage system on AWS that fully automated this workflow, combining Amazon Bedrock, AWS Lambda, and deterministic business rules to deliver accurate, auditable, and zero-touch email-to-ticket processing.
- 100%
- Automated Email Triage Achieved
- 0
- Minutes Manual Classification Time Per Email
Customer Challenges
The client's scheduling support team faced mounting operational pressure as email volumes from broadcast clients grew, and manual triage processes struggled to keep pace.

Time-Intensive Manual Triage
Each inbound email required a team member to read, interpret, classify, and manually create a Jira ticket — a process that took 5 to 10 minutes per email. With a continuous stream of scheduling requests, corrections, and information queries arriving daily, this created significant operational overhead and delayed response times.

Inconsistent Priority Assignment
Priority decisions were made manually based on individual judgment, leading to inconsistency across client tiers and SLA requirements. High-priority clients such as L1 strategic networks including NBC, CBS, FOX, and ESPN did not always receive the urgency they required, increasing the risk of SLA violations.

Duplicate Ticket Management
Without an automated duplicate detection mechanism, the same scheduling request or update was frequently logged as multiple separate tickets. This created confusion for the operations team, cluttered the Jira backlog, and made it difficult to track the true status of any given request.

Limited Audit Visibility
There was no structured audit trail linking inbound emails to the tickets they generated. This made it difficult to investigate issues, verify classifications, or demonstrate SLA compliance — creating operational blind spots across the triage workflow.
Solutions
NeenOpal built an AWS Lambda-based automation system that ingests emails from the scheduling support inbox, classifies them using Amazon Bedrock, applies deterministic business rules, and creates or updates Jira tickets — all without human intervention.
Email Ingestion via Microsoft Graph API
The system connects to the scheduling support inbox using an OAuth2 client credential flow through the Microsoft Graph API, reading unread emails every 5 minutes and processing them oldest first. Pre-filters were applied before any AI processing to skip system-generated messages, prevent self-loop emails, and exclude irrelevant recipients — ensuring only actionable emails entered the pipeline.
Content Extraction and Attachment Processing
Email content was extracted from HTML into clean plain text, and attachments across formats including Excel, CSV, PDF, Word, and TXT were downloaded, stored in Amazon S3, and processed for text content up to a 100,000 character limit. Schedule dates were extracted from attachments using AI in parallel, ensuring all relevant context was available for accurate classification.
AI Classification Using Amazon Bedrock
Amazon Bedrock powered the core classification engine, with Claude Sonnet as the primary model and Claude Haiku as a fallback. Each email was analyzed and returned a structured output including the recommended action, a confidence score between 0 and 100, the identified client name, target date, description, and action points. A low temperature setting of 0.2 ensured deterministic, consistent outputs across all classifications.
Deterministic Business Rule Overrides
AI classification was supplemented with hard business rules to enforce SLA compliance. Comscore emails were automatically forced to P1 priority with a critical label, regardless of AI output. Emails referencing past target dates were always classified as past data modifications, a rule the AI could not override. These hard overrides ensured that critical clients and time-sensitive requests were never misclassified.
Priority Matrix and Client Tier System
A structured priority matrix was applied based on client tier and target date proximity. L1 strategic networks including NBC, CBS, FOX, ESPN, and BBC received the highest priority handling with automatic owner assignment. T2 major networks and standard clients were assigned priorities based on SLA windows, ensuring consistent and defensible priority decisions across over 6,100 affiliate station mappings.
Duplicate Detection and Multi-Client Handling
A two-layer duplicate detection system using JQL fuzzy search and exact subject normalization identified existing tickets before creating new ones. Active tickets received update subtasks rather than duplicate entries, and priority could only escalate — never downgrade. Emails referencing multiple clients generated one parent ticket with independent subtasks per client, each with its own priority, assignee, and classification.
Audit Logging and Observability
Every processed email generated a complete audit trail stored in Amazon S3, including the raw email, AI extraction output, Jira payload, execution log, and all attachments. Metadata was stored in Parquet format for analytics, providing full traceability from inbox to ticket for every classification decision made by the system.
Services
 AWS Lambda
 Amazon Bedrock
 Amazon S3
 AWS Secrets Manager
 Amazon EventBridge
Benefits

100% Automated Triage
Every inbound scheduling support email was classified, prioritized, and actioned without manual intervention — eliminating 5 to 10 minutes of triage time per email and freeing the operations team to focus on higher-value work.

Deterministic Priority Assignment
The combination of AI classification and hard business rule overrides ensured that every ticket received a consistent, defensible priority based on client tier and SLA requirements — replacing subjective, inconsistent manual decisions.

Controlled Duplicate Management
The two-layer duplicate detection system significantly reduced redundant ticket creation, keeping the Jira backlog clean and ensuring that updates to existing requests were appended rather than duplicated.

Full SLA Compliance
Automated enforcement of client tier priorities, Comscore overrides, and past-date classification rules ensured that high-priority requests were never delayed or misprioritized — maintaining SLA compliance at scale.

Complete Audit Visibility
Every email and its corresponding classification, payload, and outcome were logged in Amazon S3, providing the operations team with a full, searchable audit trail for investigation, reporting, and compliance purposes.
Conclusion
By deploying an AI-driven email triage system on AWS, NeenOpal transformed the client's scheduling support operations from a manual, error-prone process into a fully automated, auditable, and SLA-compliant workflow. The combination of Amazon Bedrock-powered classification, deterministic business rule enforcement, and comprehensive S3 audit logging delivered zero-touch ticket management at scale — giving the metadata operations team the reliability and visibility they needed to support a growing network of broadcast clients with confidence.
FAQ
Here are answers to common questions about how the automation system ensures accuracy, control, and reliability in real-world operations:
How does the system handle emails that are ambiguous or low confidence?
The AI classification returns a confidence score between 0 and 100 for every email. Emails classified as "create" with a confidence above 70 result in a schedule ticket. Those below 70 are skipped and logged for review. Emails classified as "ignore" generate an Information Request ticket, with a low confidence tag added if the score falls below 30 — ensuring nothing is silently dropped.
Why were hard business rule overrides needed alongside AI classification?
AI models interpret context well but cannot be relied upon to enforce non-negotiable business rules consistently. Hard overrides — such as always assigning P1 priority to Comscore emails and always classifying past-date requests as data modifications — ensure SLA compliance in cases where the cost of misclassification is high. The principle is that AI interprets while code enforces.
How does the system prevent duplicate Jira tickets?
A two-layer duplicate detection mechanism combines JQL fuzzy search with exact subject normalization to check for existing active or closed tickets before creating a new one. If an active ticket is found, an update subtask is created instead. Priority can only escalate through this process, never downgrade, ensuring existing tickets are not inadvertently deprioritized by subsequent updates.
Authors
Case studies
Related case studies
Building a Multi-Capability Retail Customer Support Assistant on Amazon Connect
Our client, a large retail group selling consumer goods, approached NeenOpal for a customer support assistant for its website, along the lines of the conversational shopping assistants the major online marketplaces now offer. The brief arrived as an exhaustive list of capabilities the assistant had to cover, spanning product research, cart building, order tracking, warranty and complaint handling, post-purchase care, and escalation to a human agent. NeenOpal built the assistant as a working proof of concept on Amazon Connect, the first time the team had taken Connect into a customer engagement. A conversational layer handles the dialogue, a governed tool layer gives the assistant controlled access to customer and product information, verified sign-in gates anything account specific, and a handover path passes the full conversation to a live agent when a person is needed. The build went from brief to working demonstration in four weeks.
Read case study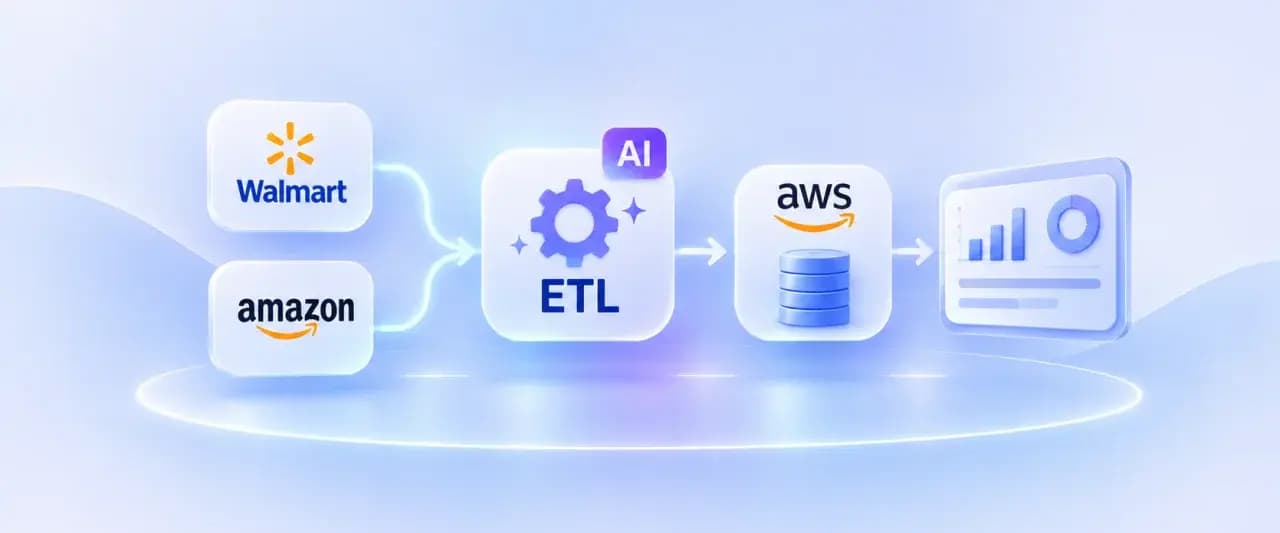
AI-Augmented ETL for Automating Multi-Portal Retail Reporting on AWS
A consumer beauty and personal care brand needed to bring its Walmart and Amazon supplier and performance data into a single AWS RDS PostgreSQL database. Walmart's data was split across a standard supplier API and three separate reporting portals (Retail Link, Scintilla, and Supplier One), each with its own authentication, file formats, and update cadence. NeenOpal designed a hybrid ETL platform with two ingestion paths running in parallel: an orchestrated API pipeline for the data Walmart exposes directly, and an AI-driven report retrieval pipeline for the data that fell outside the scope of the client's existing API access. Both paths converge on a shared Glue transformation layer, a common S3 staging area, and a single PostgreSQL database, with a separate one-time Spark job bringing in Amazon Vendor Central's historical data. The result is a single, config-driven system rather than a set of one-off integrations.
Read case study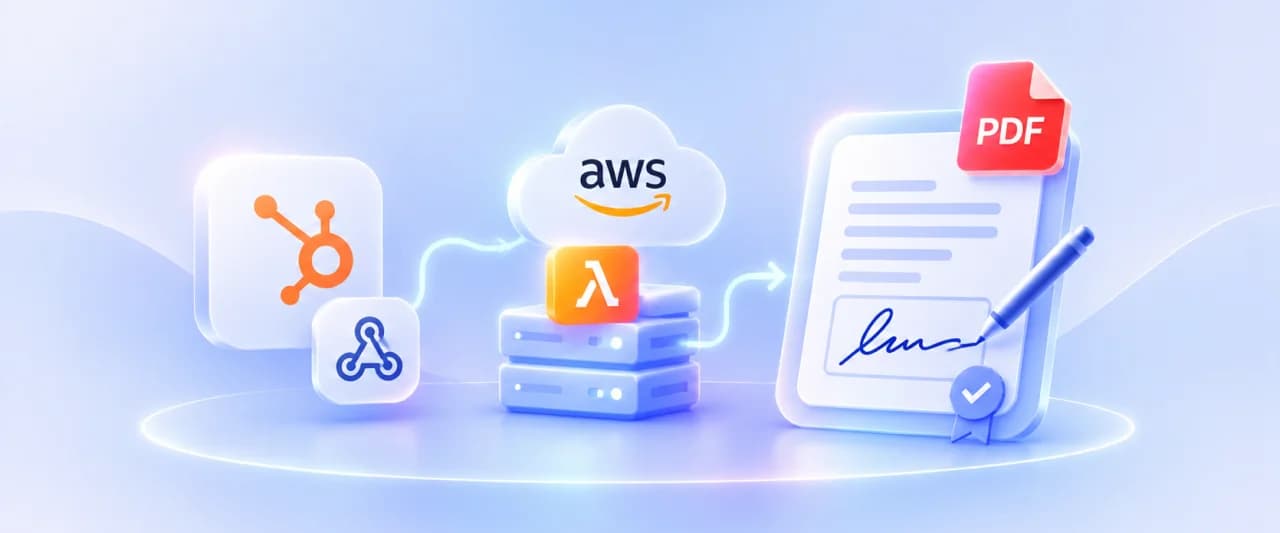
Automating Signed Credit Application PDFs with HubSpot Webhooks and AWS Serverless
Our client, a managed technology services provider, partnered with NeenOpal to automate the business credit application its customers complete when applying for credit terms. Until then the whole process ran over email. The team sent the customer a Word form as an attachment, the customer filled in their details and emailed it back, and someone then filed the completed form against the right account in Salesforce. Every application involved a round of back and forth correspondence, manual handling at both ends, and a record that existed only as a document attached to an account. NeenOpal designed and delivered HubSpot form to PDF automation on AWS, a serverless document automation pipeline that replaced the email exchange with a single link on the client's website. A customer opens the form, enters their details, and signs, and a branded PDF is generated automatically, emailed to the address captured on the form and to the client's own team, and archived in encrypted Amazon S3, while the submission itself is recorded field by field in HubSpot. Nobody sends a form out, chases it back, or files it by hand.
Read case study
Pavel Motors Automates Vehicle Repair Estimation-to-Quote Process with Claude
For automotive service businesses, moving from a repair estimate to a customer-ready quote quickly is critical, yet the process typically means manually reviewing emails and attachments, extracting repair details, checking insurance eligibility, preparing the quote, and responding to the customer. Pavel Motors partnered with NeenOpal to transform this using Claude Cowork, building an AI automotive repair quote automation solution that connects intake, document understanding, business rules, quote generation, and customer communication: when an estimate arrives by email, Claude Cowork processes it along with its attachments, extracts the relevant vehicle, repair, cost, customer, and insurance information, applies Pavel Motors' business rules, and generates a customer-ready quote while giving customers greater transparency by identifying supported insurance providers and showing the estimated amount eligible for claim coverage. NeenOpal delivered the working automation in 5 days, giving Pavel Motors a scalable way to reduce repetitive administrative work, accelerate quote turnaround, and provide a more consistent customer experience.
Read case study
Unifying Eight Disconnected Business Systems into Centralized Power BI Dashboards
Our client, a managed technology services provider (MSP), partnered with NeenOpal to replace a fragmented, siloed reporting process with a centralized Power BI dashboard environment. Business-critical data was scattered across multiple disconnected systems, from the CRM and PSA to the service desk, client surveys data, and network monitoring tools, leaving leadership without a single view of sales, customers, operations, or the workforce. NeenOpal designed and delivered a centralized Power BI reporting solution that unifies data from all of these sources into an automated, daily-refreshed analytics layer on AWS. By ingesting each source, staging it in a PostgreSQL warehouse, and modeling it into governed Power BI dashboards across every business function, the team turned manual, spreadsheet-bound reporting into interactive, self-service insight the client can filter and act on in seconds.
Read case study
Turning Foot-Traffic and POS Data into Real-Time Venue Intelligence
Our client operates a network of nightlife and hospitality venues, where each location generates massive volumes of foot-traffic and point-of-sale (POS) data every day. Without a unified way to translate this data into meaningful insights, decisions around staffing, promotions, and operations were largely reactive, cross-venue performance comparisons were nearly impossible, and revenue opportunities remained hidden inside fragmented data systems. NeenOpal partnered with the client to build a scalable, multi-tenant venue intelligence platform on AWS that transforms raw POS and footfall activity into real-time, decision-ready insights at the venue, region, and network level.
Read case study