
Overview
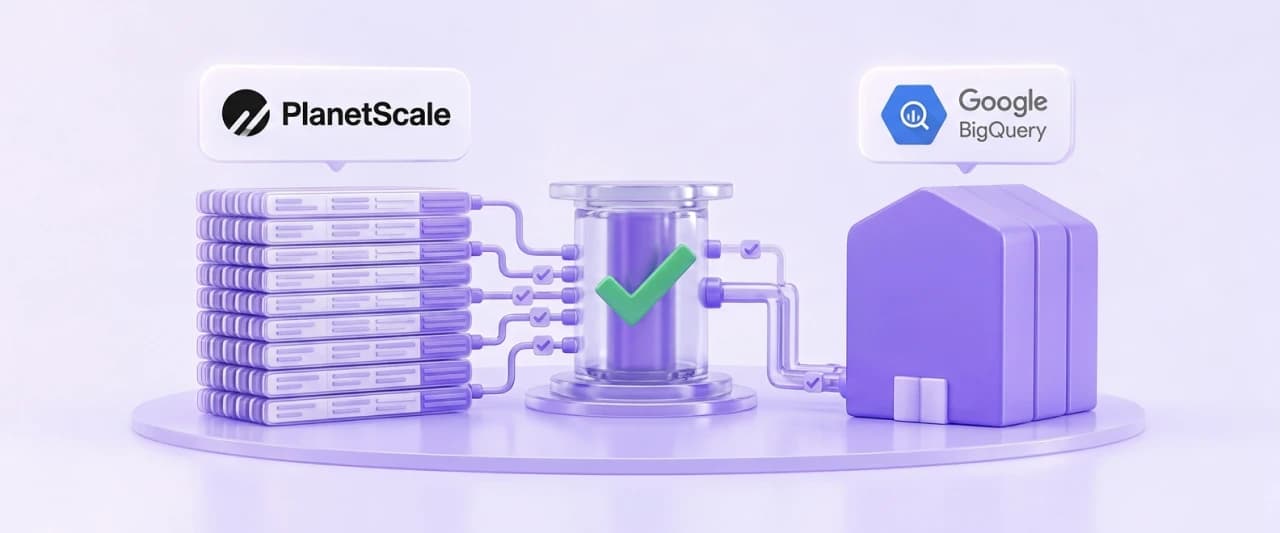
Years of user-engagement history were locked inside the production databases behind a leading dental-industry media company's websites. Every page view, article and course impression, video play and webinar interaction sat across three separate PlanetScale (MySQL) databases. There was no safe way to analyze it without slowing down the live sites. NeenOpal built a custom replication pipeline on Google Cloud Run that moved the full 170M+ row history into Google BigQuery with zero data loss, then switched to a continuous incremental sync across 12 engagement tables. The live websites never felt it: every read was routed to a read replica, away from customer traffic. A single five-minute incremental run has synced as many as 3.5M new rows.
- 170M+
- rows migrated in the historical backfill
- 3
- production databases unified into a single warehouse
- 12
- engagement tables kept in continuous, automated sync
- 500K
- rows per durable checkpoint, bounding the cost of any interruption
- 3.5M
- rows appended in a single five-minute incremental run
- 0
- data loss incidents across migration or ongoing sync
Customer Challenges
The client's most valuable audience data was also its hardest to reach. It lived in the same databases that served live web traffic, at a scale that broke the usual approaches.

Analytics vs. Live Traffic: One Database, Two Jobs
The databases holding the history were the production instances behind the client's live web properties. A conventional multi-hour extract would have competed with real users for database capacity, putting site performance at risk during the migration.

A 170M-Row Backlog With Zero Tolerance for Gaps
The backlog had to arrive complete. If a transfer stopped halfway, restarting from scratch would waste hours, and restarting from the wrong point would quietly duplicate or drop records. Either outcome would make every downstream report untrustworthy.

Long Transfers Dying to Dropped Connections
On long transfers, the database platform would silently drop connections held open while the slower destination finished writing. On tables this size, one dropped connection could throw away hours of progress. This is a common failure whenever a fast source is paired with a slower destination, and generic tools rarely handle it.

Schemas That Changed Between Runs
Product teams kept shipping features, and the tables changed with them. One table grew from 24 to 38 columns between runs. The pipeline had to absorb those changes without re-migrating history that was already loaded.
Solutions
Managed connectors assume a source that behaves like their test cases. At this scale, the failures that mattered were exactly the ones they can't control, so NeenOpal reproduced them at full scale and designed around them. The backfill and the ongoing sync run as serverless Cloud Run jobs that share one configuration and one storage layout.
Zero Impact on the Live Websites
Every extraction reads from PlanetScale's read replica, never the primary. A multi-hour migration across hundreds of millions of rows ran without competing with real users for database capacity.
Streaming Extraction That Scales to Any Table Size
A custom exporter combines server-side cursors with key-based (keyset) pagination, so rows stream straight into Google Cloud Storage. Memory stays flat whether a table holds 10,000 rows or 50 million, and the pipeline never loads a full table at once.
Checkpoints Every 500,000 Rows, so a Failure Costs Minutes, Not Hours
Progress is saved only after each half-million-row file is safely written. If a run is interrupted by a timeout or a dropped connection, it resumes from the last saved file, with no duplicates and no gaps. Each table also runs in isolation: one failure is logged and skipped without stopping the others, and any table can be re-run on its own.
Schema Changes Absorbed Without Reloading History
Data lands in BigQuery as text first and is typed later in the reporting layer, so malformed dates, embedded HTML or stray line breaks can't break a load. When one table gained 14 columns mid-project, recovery was a single schema update over the existing files, with no reload of migrated rows.
One Repeatable Path for Every Table
All 12 engagement tables follow the same route: a streamed extract from the read replica, immutable files in Cloud Storage that are written once and never changed, and BigQuery tables on top. Adding a new table is configuration, not new engineering.
Self-Healing Incremental Sync
After the backfill, the pipeline switched to scheduled incremental runs. Each run reads its starting point from BigQuery itself rather than a separate state file, so an interrupted or lost run recovers on the next schedule with no manual intervention.
Services
 Python
 Google BigQuery
 Google Cloud Run
 Google Cloud Storage
 MySQL
Benefits

Years of Audience Behavior, Finally Usable
Engagement history that had only ever powered the live sites now sits in BigQuery, ready for audience segmentation, content performance analysis and advertiser reporting across the client's brand portfolio.

Complete, Trustworthy Data From Day One
The full 170M+ row backlog arrived with no duplicated or missing records, verified against source row counts at every stage. Reports built on it can be acted on without second-guessing the numbers.

No Risk to the Live Business During Migration
Routing every read to the read replica meant the migration added no load to the databases serving customers. Site performance was never part of the trade-off.

Data That Stays Current Without Anyone Watching It
The incremental sync recovers from interrupted runs on its own and appended 3.5M rows in a single five-minute run. The client's team doesn't manage cursors, restart jobs or babysit transfers.

Built to Keep Up as the Product Changes
The pipeline absorbed new columns, upstream outages and the move from one-time migration to continuous sync without a redesign. As the source evolves, the pipeline keeps running.
Conclusion
By designing around the real limits of the source platform instead of forcing a generic tool to fit, NeenOpal moved 170M+ rows into BigQuery without loss and without touching live site performance. The same pipeline now feeds engagement analytics across the client's brand portfolio. It extends the marketing data warehouse described in Unified Cross-Platform Intelligence Across 20+ Data Sources.
FAQ
Your Questions About MySQL to BigQuery Replication, Answered
How do you migrate data from PlanetScale MySQL to BigQuery without affecting the live website?
Every extraction reads from PlanetScale’s read replica, never the primary database. The migration doesn’t compete with real users for database capacity, so site performance stays the same throughout.
How much data was migrated, and was any of it lost?
The historical backfill moved more than 170 million rows from three production databases into BigQuery with zero data loss. Row counts were verified against the source at every stage, so there were no duplicated or missing records.
What happens if a large data transfer fails partway through?
The pipeline saves a checkpoint after every 500,000 rows are safely written. An interrupted run resumes from the last saved file, so a failure costs minutes instead of hours, with no duplicates or gaps. Each table also runs on its own, so one failure doesn’t stop the others.
Why not use a managed connector for PlanetScale to BigQuery replication?
Managed connectors struggle at this scale with the specific limits of the source, such as dropped connections on long transfers and frequent schema changes. A custom pipeline on Google Cloud Run was designed around those failure points.
Authors
Madhumita GiribabuSenior Associate Consultantin
Case studies
Related case studies
Turning Foot-Traffic and POS Data into Real-Time Venue Intelligence
Our client operates a network of nightlife and hospitality venues, where each location generates massive volumes of foot-traffic and point-of-sale (POS) data every day. Without a unified way to translate this data into meaningful insights, decisions around staffing, promotions, and operations were largely reactive, cross-venue performance comparisons were nearly impossible, and revenue opportunities remained hidden inside fragmented data systems. NeenOpal partnered with the client to build a scalable, multi-tenant venue intelligence platform on AWS that transforms raw POS and footfall activity into real-time, decision-ready insights at the venue, region, and network level.
Read case study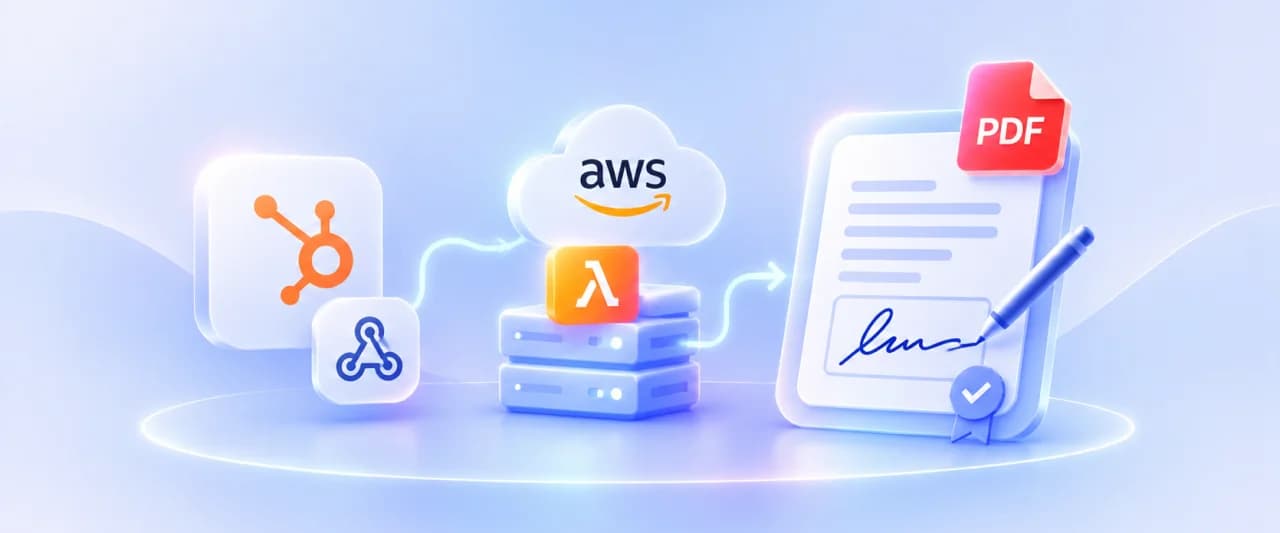
Automating Signed Credit Application PDFs with HubSpot Webhooks and AWS Serverless
Our client, a managed technology services provider, partnered with NeenOpal to automate the business credit application its customers complete when applying for credit terms. Until then the whole process ran over email. The team sent the customer a Word form as an attachment, the customer filled in their details and emailed it back, and someone then filed the completed form against the right account in Salesforce. Every application involved a round of back and forth correspondence, manual handling at both ends, and a record that existed only as a document attached to an account. NeenOpal designed and delivered HubSpot form to PDF automation on AWS, a serverless document automation pipeline that replaced the email exchange with a single link on the client's website. A customer opens the form, enters their details, and signs, and a branded PDF is generated automatically, emailed to the address captured on the form and to the client's own team, and archived in encrypted Amazon S3, while the submission itself is recorded field by field in HubSpot. Nobody sends a form out, chases it back, or files it by hand.
Read case study
Predicting Video Revenue Through Marketing Mix Modeling and Bayesian Forecasting
Our client, a media and entertainment company, sought to establish a scalable and repeatable process to predict video revenue based on varying marketing spend inputs. With multiple upcoming releases and limited visibility into which marketing channels drove the most impact, media planning decisions were largely manual and difficult to optimize. The client partnered with NeenOpal to operationalize a Marketing Mix Modeling (MMM) framework, enabling data-driven revenue forecasting, dynamic sensitivity analysis, and interactive scenario planning through a Tableau dashboard.
Read case study
Unlocking Instant Cash Flow for Businesses Using AR Factoring Platform
The client partnered with NeenOpal to build a modern AR Factoring platform tailored for gas station businesses in the fuel and energy retail sector. The objective was to enable faster access to working capital by advancing funds against card-based receivables, while maintaining strong risk controls, compliance, and operational scalability. NeenOpal brought this vision to life by designing a fully automated, cloud-native solution that seamlessly manages onboarding, funding, repayment, and auditability.
Read case study
Automated Ticket Invoice Processing & Analytics Using AWS Textract and Redshift
A media and event-driven organization managing high-volume ticket sales receives periodic ticket invoices via email from multiple vendors and booking partners. These invoices arrived in semi-structured and unstructured formats (PDFs, scanned images, email attachments), making manual processing time-consuming, error-prone, and non-scalable. To address this, we designed and implemented a fully automated, serverless data pipeline on AWS that ingests invoices from email, extracts structured data using OCR, Custom Scripts, and NLP, stores curated datasets in Amazon S3, and loads analytics-ready data into Amazon Redshift. This enabled descriptive analytics and downstream ticket sales forecasting with strong governance, observability, and cost efficiency.
Read case study
Autonomous Metadata Enrichment with Agentic AI
Our client, a prominent entertainment company, faced persistent delays and quality issues caused by incomplete metadata within critical content systems. Manual efforts to validate and enrich records created bottlenecks and limited scalability. We built an autonomous data enrichment solution using agentic AI that detects missing fields, extracts reliable information from trusted sources, and updates databases with validated, confidence-scored insights.
Read case study