
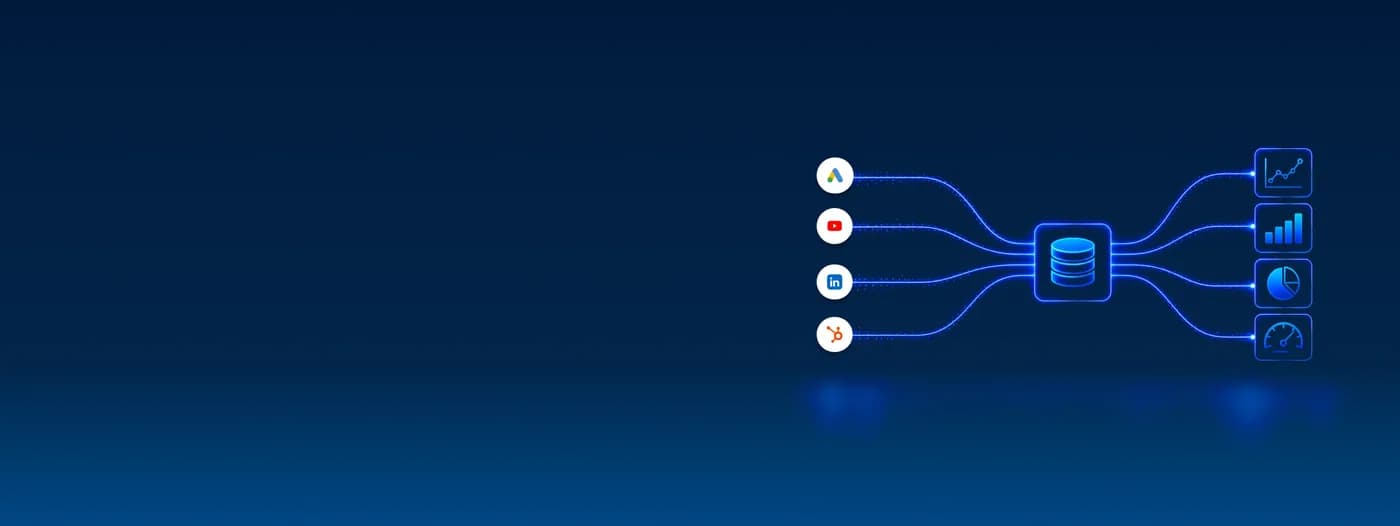
Data Pipeline Engineering That Unifies Scattered Sources
NeenOpal's data pipeline engineering services bring scattered sources like Google Ads, YouTube, LinkedIn, and HubSpot into one governed table or view your reporting can trust, with error handling, notifications, and retry logic built in.
Partners
What we cover
What Our Data Pipeline Engineering Services Cover
Every engagement starts the same way: map what you have, then build the layer that gets it into one place you can trust. Here's what that covers.
ETL & ELT Pipeline Development
We build ETL or ELT pipelines depending on your warehouse, data volume, and latency needs, using orchestration tools like Apache Airflow and transformation frameworks like dbt to keep the logic version-controlled and testable.
Multi-Source Consolidation
Google Ads, YouTube, LinkedIn, HubSpot, and whatever else your stack runs on get pulled into one governed table or view, so reporting stops depending on which source someone happened to check.
Batch & Streaming Pipelines
Scheduled batch loads for standard reporting, and streaming pipelines on tools like Kafka, Kinesis, or Azure Stream Analytics when a use case like live inventory or transaction monitoring needs data as it happens.
Orchestration & Reliability
Every pipeline runs on an orchestrated schedule with error handling, retries, and run-status alerts built in, not added after something breaks.
Data Quality & Observability
Automated checks and full observability into every run, so a failure is caught and understood in minutes, not discovered days later in a stale report.
Incremental Loads & Backfills
Change data capture and incremental loads keep your warehouse current without reprocessing full history, and a historical backfill runs through the exact same tested pipeline as new data.
Outcomes
Outcomes Enterprise Leaders Measure Us By
- Financial Impact Delivered to Clients
- $750M+
- Reached North Star outcomes within 90 days
- 85%
- Faster Go-to-Market With AI Acceleration
- 8X
- Cloud cost savings across operations
- 60%
Reliability
How We Keep Pipelines Reliable and Trustworthy
The most common problem we inherit is a pipeline that fails silently, or one that runs fine but is quietly consolidating messy source data. Reports run for days on numbers nobody knows are wrong. We build against both from day one.
Failure handling & retries
Every pipeline step catches its own failures in code, so one bad batch never takes down the whole run. Transient failures trigger an automatic, idempotent retry on their own, so a rerun never double-counts data.
Alerts & runbooks
Automated alerts flag every failed or completed run as soon as it happens, giving you full observability into pipeline health. Every pipeline also ships with a clear runbook, so any engineer, ours or yours, can diagnose an issue fast.
Schema variability across sources
Clients often use different tables and features in the same tool, so we build around their actual setup. When two sources carry different data models, like CRM records and analytics events, we map both into one schema first.
Multi-value and incomplete fields
When a record carries multiple values, like two phone numbers or emails per customer, we consolidate them cleanly in the warehouse without duplicates. Where fields are missing, we alert the owning team with a direct link to complete them.
Legacy-to-new system consolidation
When data needs to move out of a legacy system and merge with what's replacing it, we carry the full history across intact, so the new system's reporting is complete from day one.
Source-of-truth reconciliation
We agree on a source of truth with the client up front, then trace every number in the final report back through each transformation to that source, so the lineage behind a figure is never a guess.
Watch
Hear It From the People Who Build Your Pipelines
NeenOpal's data engineers sit down for an unscripted conversation on what actually breaks in data pipelines, where AI genuinely helps in BI, and what a source-to-report data journey looks like in practice. It's a practical, on-the-ground look at the same reliability and consolidation work described above, from the people who build it.
Reporting layer
Reporting Pipelines Shaped to the Question
A pipeline is only as good as the question it answers. We design the reporting layer around your actual business question. On the same engagement, that meant three possible distinct reporting pipelines.
Lifecycle view
Answers how a single lead or cohort performs from start to finish. One pipeline follows it the whole way, to closure or drop-off.
Active-now view
Answers how everything active is performing right now. A separate pipeline pulls every currently active lead into one live monthly view.
Trend view
Answers whether performance is moving up or down over time. It compares the same metric month over month or quarter over quarter.
Data engineering
Related Data Engineering Services
At NeenOpal, we build data engineering solutions end-to-end, from raw, scattered source systems to clean, governed pipelines your business can reliably run on.
Data Warehouse Modernization Services
Modernizing legacy data warehouses into scalable, cloud-native architectures built for speed and governance.
Learn moreData Strategy & Architecture Services
Defining the data strategy, governance, and architecture roadmap that aligns data with business goals.
Learn moreData Platform Engineering Services
Architecting scalable, secure data platforms that unify your organization's data for AI and reporting.
Learn more
Engagement models
Choose the Engagement Model That Fits Your Needs
Managed Architecture Engagement
A dedicated data architect plus the full team your rollout needs, owning the assessment, target-state architecture, governance design, and handover end-to-end.
Book an architecture reviewArchitects on Your Team
Certified AWS and Azure architects join your existing team for the migration, governance modeling, or platform work you don't have in-house bandwidth for.
Find available data architectsFixed-Scope Architecture Assessment
One estate assessed, fixed scope, fixed price, and milestone-based delivery, so you know the cost, timeline, and outcome before work begins.
Get an assessment estimate
Case studies
Related Case Studies
Automated Data Validation & ADF Pipelines for a Healthcare Organization
The client, a leading healthcare organization, initially used Excel to manage critical data. They approached NeenOpal to build a more reliable backend system using Azure SQL that would improve data consistency, reduce manual work, and support better data control. The project focused on setting up strong validation rules, automated processes, and referential integrity features like cascading updates to create a scalable, accurate, and future-ready data environment.
Read case study
Automated ERP ETL Pipeline for Global Manufacturing Reporting
Our client, a global leader in the manufacturing sector specializing in welding consumables and machinery, operates in over 100 countries with a network of more than 30 subsidiaries, delivering exceptional service and support worldwide. To enhance their operations, NeenOpal designed Tableau dashboards currently utilized across four regions and 26 countries, supporting a geographically diverse user base.
Read case study
Cloud ETL Pipeline for Dr. Sum Replacement in Financial Reporting
A global manufacturing organization with regional headquarters in the United States operates across various sectors, including agriculture, construction, marine, and industrial. The company produces advanced diesel engines, diesel-powered equipment, and gas engine-based energy systems, with finance operations supporting complex, high-volume ERP-driven reporting needs.
Read case study
Client reviews
What clients say about working with us
Each member of the team is interested and knowledgeable about the process!
NeenOpal Intelligent Solutions is understanding and invests heavily in the project at hand. The engagement resulted in an optimized inventory and increased sales, meeting the expectations of our internal team!
 Kapila PereraIT DirectorSinger Sri Lanka PLCVerified review on Clutch
They are attentive to detail and have shown us they can solve difficult problems.
We’re excited to partner with NeenOpal for their collaborative approach, on-time delivery, clear communication, and attention to detail. Their ability to solve complex problems, paired with creative design and forward thinking, sets them apart.
 Joyce Ann McGinnFounder & COOCompris, Inc.Verified review on Clutch
I like that the team is incredibly hard-working, talented, and good with people.
NeenOpal is a hard-working, talented team that consistently brings fresh ideas. Their domain experience reshaped our MIS reporting and delivered deeper insights, helping us approach complex business challenges with greater clarity and improved resource productivity.
 Saransh ChaudharyCEOVenus Remedies LimitedVerified review on Clutch
NeenOpal delivers high-accuracy analytics that drive reliable, KPI-driven outcomes.
It’s been a pleasure working with NeenOpal from the outset. They delivered our data lake on time and consistently demonstrate high numerical accuracy and strong analytical expertise. By meeting key KPIs, they support smooth operations and measurable business outcomes.
 Saurabh BholaCTOThe Healthy Mummy Pvt. Ltd.Verified review on Clutch
Bring your scattered sources into one trusted table
Tell us which sources feed your reporting today and where the numbers drift. A data engineer will follow up with next steps.
FAQ
Data Pipeline Development Services FAQs
Straight answers on how NeenOpal designs and supports data pipeline engineering services built for reliability.
What are data pipeline development services?
They cover designing, building, and running the pipelines that move data from your source systems into a warehouse or reporting layer, including the error handling, monitoring, and governance that keep it running unattended.
Do you offer both ETL development services and ELT pipeline development?
Yes. We choose ETL or ELT based on your warehouse, data volume, and latency needs, then build the transformation logic wherever it performs best, inside the pipeline or inside the warehouse.
Can you build real-time data pipeline services for streaming data?
Yes. For use cases like live inventory, transaction monitoring, or event tracking, we build streaming pipelines on tools such as Kafka, Kinesis or Azure Stream Analytics, with the same alerting and retry logic as our batch pipelines.
Do I need a data pipeline consultant, or can your team just build it?
Most engagements start with a short consulting phase where we map your sources and define the target architecture. The same team then delivers a fully documented, custom data pipeline development project, so nothing gets lost in handoff.
How long does a data pipeline development services engagement take?
A single consolidation pipeline with reconciliation and alerting usually ships in four to eight weeks. Multi-source projects with governance and historical backfill run longer, and we confirm exact timelines after the first architecture review.